

Heights of adults, errors in a measurement, scores on large standardized tests: plot enough data of this kind and a familiar shape tends to appear, high in the middle and tapering off symmetrically on both sides. This is the normal distribution, often called the bell curve. It is one of the most important ideas in statistics, and understanding it makes it easier to read research, interpret test scores, and make sense of data in everyday life.
What is a normal distribution?
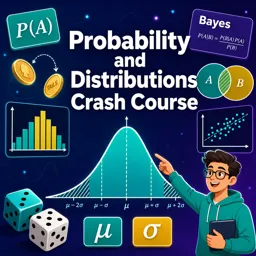
A normal distribution is a continuous probability distribution that is symmetric around its center. Most values cluster near the mean, and the further you move from the mean in either direction, the fewer values you find. The mean, median, and mode all sit at the same point in the middle.
Two numbers completely describe any normal distribution:
- The mean (μ): the center of the curve, which determines where it sits on the number line.
- The standard deviation (σ): a measure of spread, which determines how wide or narrow the bell is.
A small standard deviation produces a tall, narrow bell, meaning values are tightly packed around the mean. A large standard deviation produces a flatter, wider bell, meaning values are more spread out.
The 68-95-99.7 rule
One of the most useful facts about the normal distribution is the empirical rule. It tells you roughly what share of the data falls within a given number of standard deviations from the mean:
| Range | Approximate share of data |
|---|---|
| Within 1 standard deviation of the mean | 68% |
| Within 2 standard deviations | 95% |
| Within 3 standard deviations | 99.7% |
Suppose a quiz has scores that are approximately normal with a mean of 70 and a standard deviation of 10. Then about 68% of students scored between 60 and 80, about 95% scored between 50 and 90, and almost everyone scored between 40 and 100. A score of 95 would be unusual, because it lies two and a half standard deviations above the mean.
Z-scores: comparing values on the same scale
A z-score tells you how many standard deviations a value is from the mean. The formula is simple:
z = (x − μ) / σ
Using the previous example, a score of 85 gives z = (85 − 70) / 10 = 1.5. This means the score is one and a half standard deviations above the mean. A negative z-score means the value is below the mean.
Z-scores are powerful because they let you compare results from different scales. Imagine a student who scored 85 on a test with a mean of 70 and a standard deviation of 10, and 78 on another test with a mean of 65 and a standard deviation of 5. The first z-score is 1.5; the second is (78 − 65) / 5 = 2.6. Relative to their classmates, the student performed better on the second test, even though the raw score was lower.
Why does the bell curve appear so often?
The main reason is the central limit theorem. In simple terms, when you add up or average many small, independent influences, the result tends to be approximately normally distributed, even if the individual influences are not. A person’s height, for example, is shaped by many genes and environmental factors, each contributing a small amount. The combined effect tends to produce a bell shape.
This theorem also explains why averages of random samples behave predictably. If you repeatedly take samples from a population and compute each sample’s mean, those means tend to form a normal distribution. That property is the foundation for confidence intervals and many hypothesis tests.
Real-world uses
- Quality control: manufacturers monitor whether product measurements stay within acceptable limits of the mean.
- Education and testing: many standardized scores are reported using means and standard deviations, so students can see how they compare with others.
- Science: measurement errors are often modeled as normally distributed noise.
- Health: growth charts and reference ranges frequently rely on how values are distributed in a population.
Not everything is normal
It is tempting to assume every dataset is bell-shaped, but many are not. Income and wealth are usually skewed, with a long tail of very high values. The time between events, such as customer arrivals, often follows a different pattern. Data with extreme outliers, like stock market crashes, can have heavier tails than a normal distribution predicts.
Before applying normal-distribution tools, it helps to check the shape of your data. A histogram is a quick first step: look for symmetry, a single peak, and a gradual decline on both sides. If the plot is strongly lopsided or has several peaks, a different method may be more appropriate.
Common mistakes to avoid
- Assuming normality without checking. Always visualize the data first.
- Confusing the standard deviation with the range. The standard deviation measures typical distance from the mean, not the gap between the minimum and maximum.
- Applying the 68-95-99.7 rule to skewed data. The percentages only hold approximately for bell-shaped distributions.
- Treating a z-score as a percentage. A z-score of 1.5 does not mean 1.5%; it means 1.5 standard deviations from the mean.
Conclusion
The normal distribution is a practical tool for describing how data spreads around an average. With just a mean and a standard deviation, you can estimate how common or unusual a value is, compare results across different scales, and understand why sample averages are so reliable. To keep building your skills in statistics and data analysis, take a look at the related courses available on Cursa.